A 2026 technical guide to GPU inference performance covering prefill vs decode bottlenecks, KV cache memory bandwidth, continuous batching, quantization, and MLPerf benchmark data for H100, H200, B200, and MI300X.
IntuitionLabs is now a member of the Claude Partner Network – AI training and upskilling with Claude for pharma and biotech. Book a call.

A 2026 technical guide to GPU inference performance covering prefill vs decode bottlenecks, KV cache memory bandwidth, continuous batching, quantization, and MLPerf benchmark data for H100, H200, B200, and MI300X.

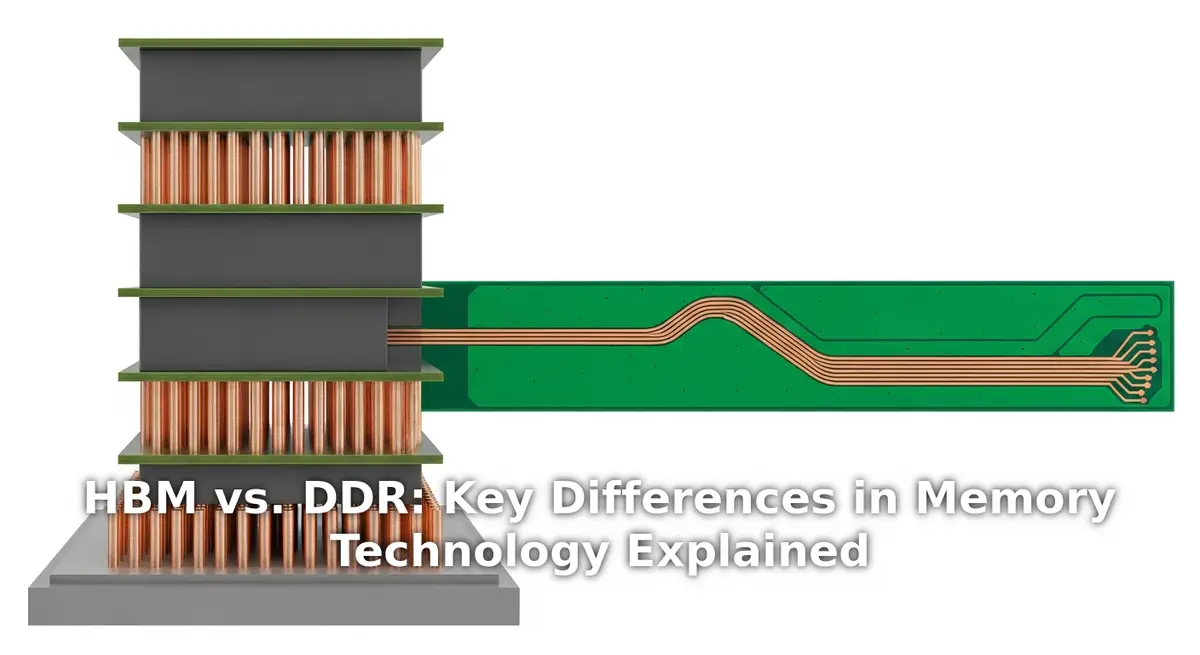
Learn the key differences between High Bandwidth Memory (HBM) vs. DDR. Explore HBM's 3D architecture, HBM3E/HBM4 generations, bandwidth benefits over DDR5, and its role in AI & HPC GPUs (NVIDIA Blackwell, AMD MI350).

DDR6 is still in JEDEC development. We explain its reported 8,800-17,600 MT/s targets, proposed 4x24-bit channels, likely release window, and how it compares to DDR5 for AI and HPC.
© 2026 IntuitionLabs. All rights reserved.